Convert English Digit Words in Java with String.replace
For valid input mixing digits with digit words, replace the fixed words zero through nine with digits, then parse the resulting integer. The search terms are literals, so String.replace is sufficient without replaceAll.
The exercise guarantees valid lowercase digit words and digits, a result from 1 to 2,000,000,000, and no leading zero. This is not a parser for general English number expressions.
Processing flow
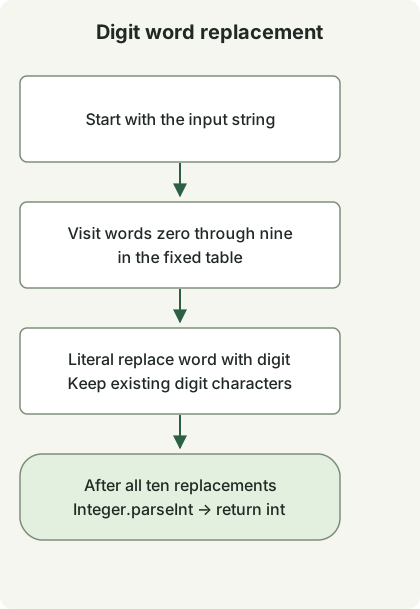
Replace the fixed words zero through nine with literal digits, then parse the resulting decimal string.
Replace the ten fixed words
Save the full class as Solution.java. No additional imports are needed; it was compiled and executed with a Java 11 target.
public class Solution {
    public int solution(String s) {
        String[] words = {"zero", "one", "two", "three", "four",
                "five", "six", "seven", "eight", "nine"};
        for (int digit = 0; digit < words.length; digit++) {
            s = s.replace(words[digit], Integer.toString(digit));
        }
        return Integer.parseInt(s);
    }
}
String.replace(CharSequence, CharSequence) performs literal replacement. replaceAll interprets its first argument as a regular expression. None of the ten words requires regex syntax here.
For example, one4seveneight becomes 1478, and 23four5six7 becomes 234567. Input already containing only digits, such as 123, still yields 123. two followed by nine zero words yields 2,000,000,000, within int range.
Replacement digits cannot introduce another digit word, and none of these ten words contains another word in the set, so this order works. Invalid words, spaces, uppercase input, and out-of-range numbers are outside the exercise’s guarantees. A parse failure on arbitrary input is not repaired into a valid integer by this method.
With ten fixed words, time is O(n) in input length. Strings are immutable, so intermediate replacement strings may be allocated; additional space is O(n). No benchmark establishes this method as faster than other parsers for these small inputs.
Compare new ID normalization for a transformation where regular expressions are useful.
Discussion